In May 2026, Google announced it would stop supporting FAQ-rich results altogether: no more expandable question-and-answer snippets in search, no more reporting on them in Search Console, the Rich Results testing tool dropping support by June, and API support gone by August. Google announced in May 2026 that it would stop supporting FAQ-rich results entirely, and a lot of teams are going to read that as permission to stop bothering with FAQ content altogether.
That's the wrong lesson. Google killed a specific SERP feature. It didn't kill the underlying value of a question written clearly next to a direct answer, and that's exactly the shape ChatGPT, Perplexity, Gemini, and the rest are looking for when they're deciding what to lift into an answer and cite. The zero-click search didn't go away because one search engine stopped showing a widget. If anything, the gap between a page that's easy for a model to extract from and one that isn't matters more now than it did when Google's rich snippet was doing some of that work for you.
FAQ schema was never really about Google's snippet
Bing, Perplexity, and several other AI-driven tools still read FAQPage structured data directly. Removing it because Google stopped displaying it would be optimizing for a single consumer of your markup instead of all of them. The schema itself isn't the problem. What's actually broken on most FAQ pages is the content underneath it, and that was true before Google's announcement too.
What a human-skimming FAQ looks like, and why it fails extraction
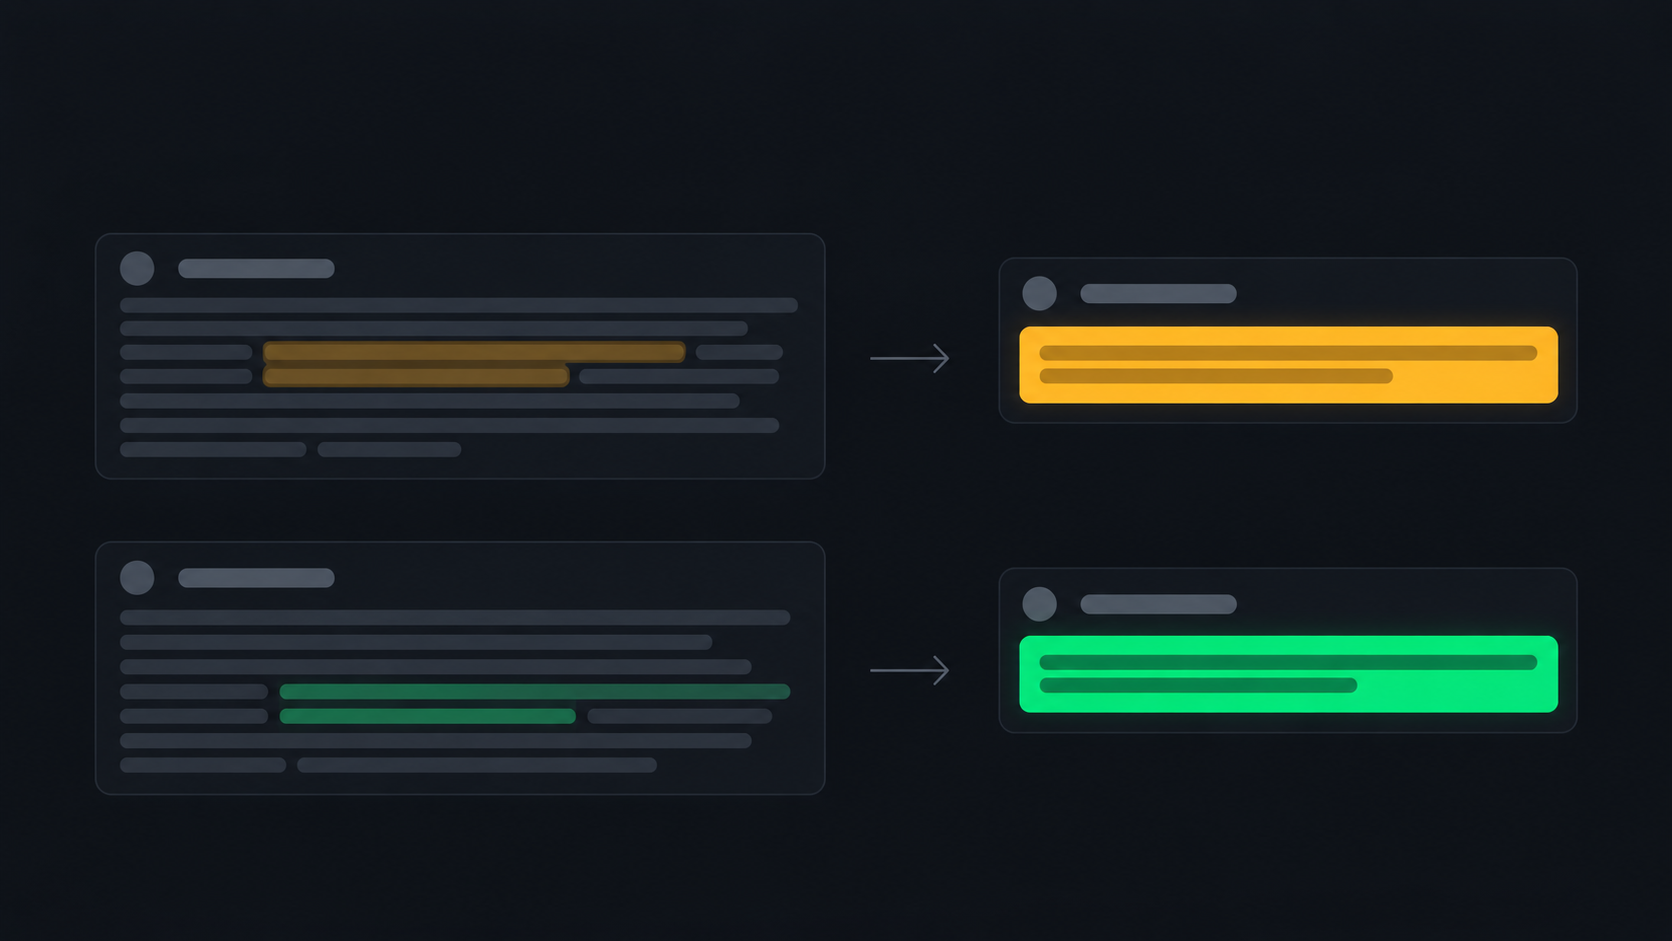
Most FAQ pages are written like brochures, with a friendly question followed by two or three sentences of background information and then the actual answer to the question. This type of copy can be “skimmed” by a human reader who will ignore the “fluff” between the background information and the call to action for the product being promoted. However, the model will have problems in determining where the actual answer to the question begins and ends, and a very “wordy” answer can be misquoted, “trimmed” to lose the point of the answer, or even ignored in favor of a competing answer that is worded better.
By contrast, a structured answer is written as a real human would have written it. The question is phrased naturally as you would type or speak it—not as some arbitrary label a copywriter may have used for a section. The direct answer to the question is then provided immediately after the question, within a single block of text containing just one fact. The subsequent support and marketing copy can then follow.
The practical differences that matter
Instead, match the question to real wording (as opposed to cleaned-up versions). So “What is the waiting period for pre-existing conditions?” is a much better question and answer than “Understanding Our Coverage Policies.”
Answer first, explain second. For example, 'Yes, but only after 24 months’ is a much better answer than ‘Understanding Our Coverage Policies.' This is because the reader immediately understands the answer and then can read the rest of the sentence to understand why.
Keep the FAQPage schema even if Google doesn’t display the rich result anymore, as Google doesn’t charge anything for it, and other search engines like Bing as well as several AI tools like to parse it directly.
Duplicated, thin, and templated content on different pages also represents a problem for models. As for humans, no one likes to read same-looking copied answers to identical questions on different pages. It looks like spam. And if all answers on all pages sound similar, then you haven’t actually answered twenty different questions.
Keep your answers up to date and regularly check them for accuracy. Stale information, no longer accurate, left for years to decompose could be misleading to a user or worse, be quoted with incorrect numbers or policy statements attributed to you.
Where this fits
This is the tactical layer underneath the entity-graph approach we wrote about for schema more broadly: the entity graph tells a model what your brand is and does across the whole site, and well-structured answers are what actually gets pulled and quoted once a model has decided your site is worth drawing from. One without the other leaves something on the table. If you want a page-by-page read on which of your FAQ content is extraction-ready and which is quietly costing you citations, that's part of the GEO work we run for clients.